Learning Environment for OpenAI Gym
Move the player (yellow object) to avoid the bullet from the enemy (blue object). The goal is to keep the bullets avoid. v0 moves in the vicinity of 8. v1 only moves horizontally.
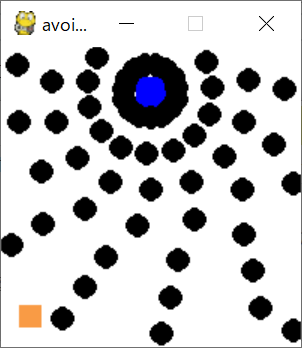
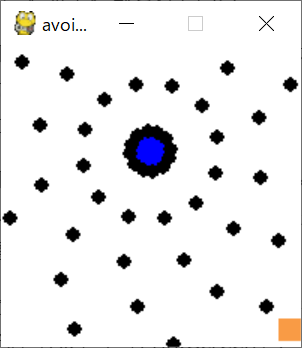
The left of the above figure is task1(t1).The right of the above figure is task2(t2).
- avoid_game_t1-v0
- avoid_game_t1-v1
- avoid_game_t2-v0
- avoid_game_t2-v1
Numpy array of screen RGB pixel values
shape(200, 200, 3) dtype=np.uint8
Min 0
Max 255
Type: Discrete(9)
| Num | Action |
|---|---|
| 0 | Player don't move |
| 1 | Player moves to the up |
| 2 | Player moves to the up right |
| 3 | Player moves to the right |
| 4 | Player moves to the down right |
| 5 | Player moves to the down |
| 6 | Player moves to the down left |
| 7 | Player moves to the left |
| 8 | Player moves to the up left |
Type: Discrete(3)
| Num | Action |
|---|---|
| 0 | Player don't move |
| 1 | Player moves to the left |
| 2 | Player moves to the right |
Reward 1 per step survival
The episode ends when the player is hit
git clone https://github.com/5h00T/avoid_game_env/
cd avoid_game_env/
pip install -e .
import time

import gym_avoid_game
import gym


env = gym.make("avoid_game_t1-v0")
# env = gym.make("avoid_game_t1-v1")
# env = gym.make("avoid_game_t2-v0")
# env = gym.make("avoid_game_t2-v1")
obs = env.reset()
done = False
while not done:
    env.render()
    # time.sleep(0.016)

    action = env.action_space.sample()
    obs, reward, done, _ = env.step(action)